LLM Evaluation
2 articles
A model can score well on a public benchmark and still fail on your data. Useful evaluation starts with the decisions your system must make, the cost of an incorrect answer, and the latency your users can tolerate.
These articles connect that evaluation process to a worked model comparison. Read the production guide to define your tests, then use the Laya and Jev benchmark to see how accuracy, calibration, and latency can lead to different choices.
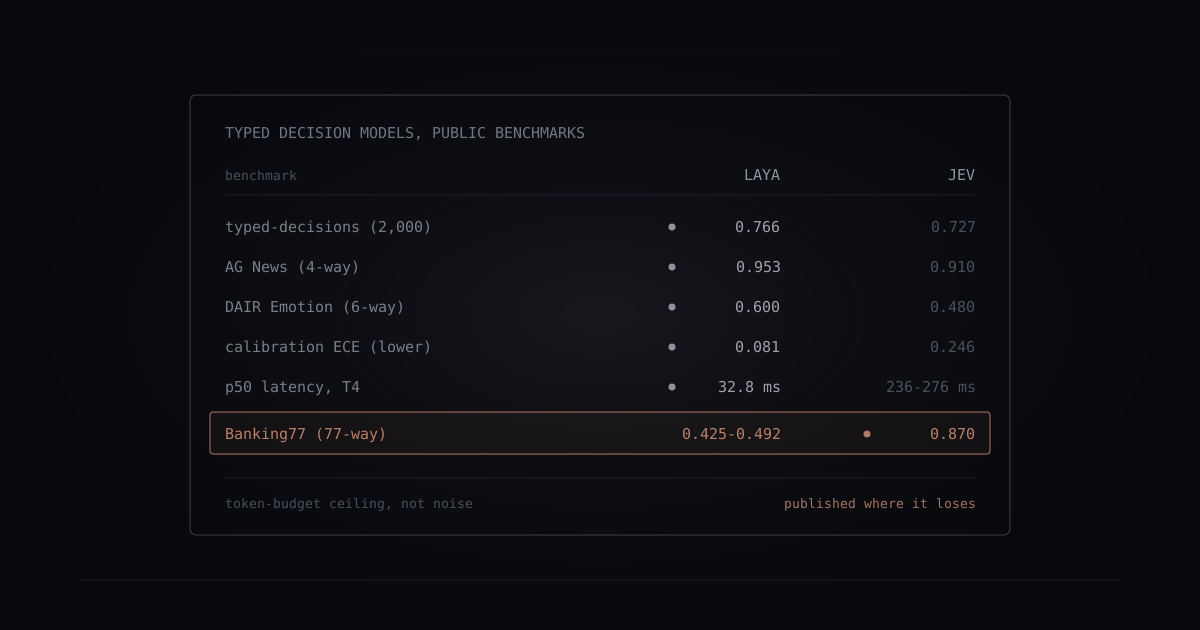
Laya vs Jev: an open-source benchmark of typed decision models
We benchmarked open-source Laya against TypeSafe's Jev on public datasets and internal scenarios: accuracy, latency, calibration, and where each wins.
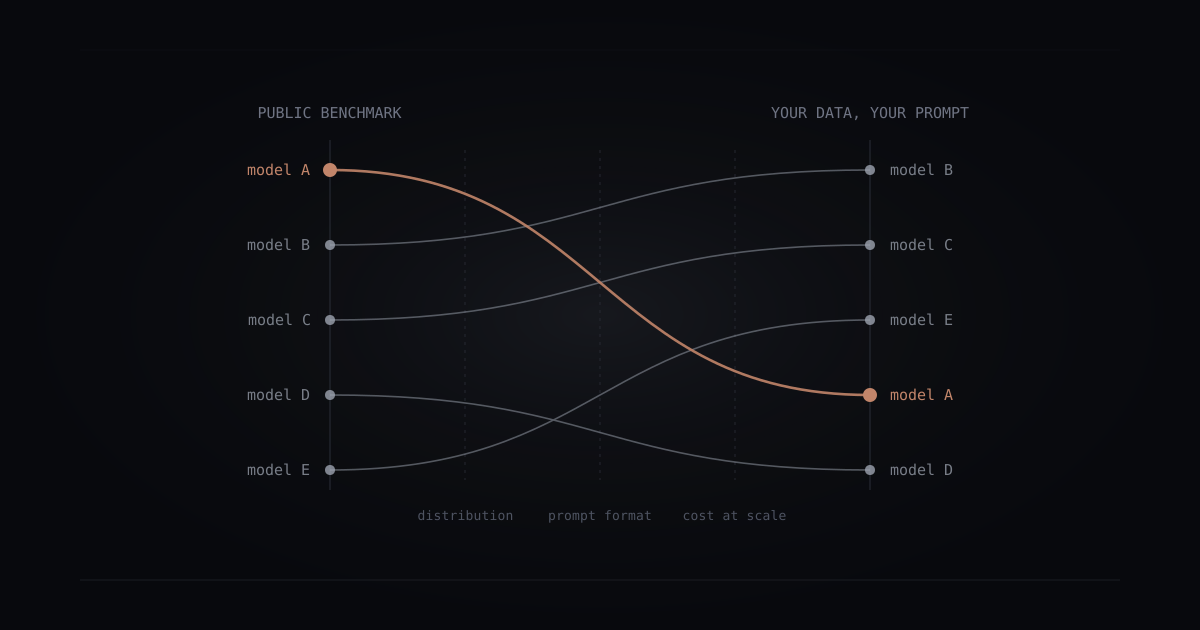
Evaluating LLMs for production: what benchmarks don't tell you
Public benchmarks measure models under controlled conditions. How to build an evaluation on your data and quality criteria that predicts production outcomes.