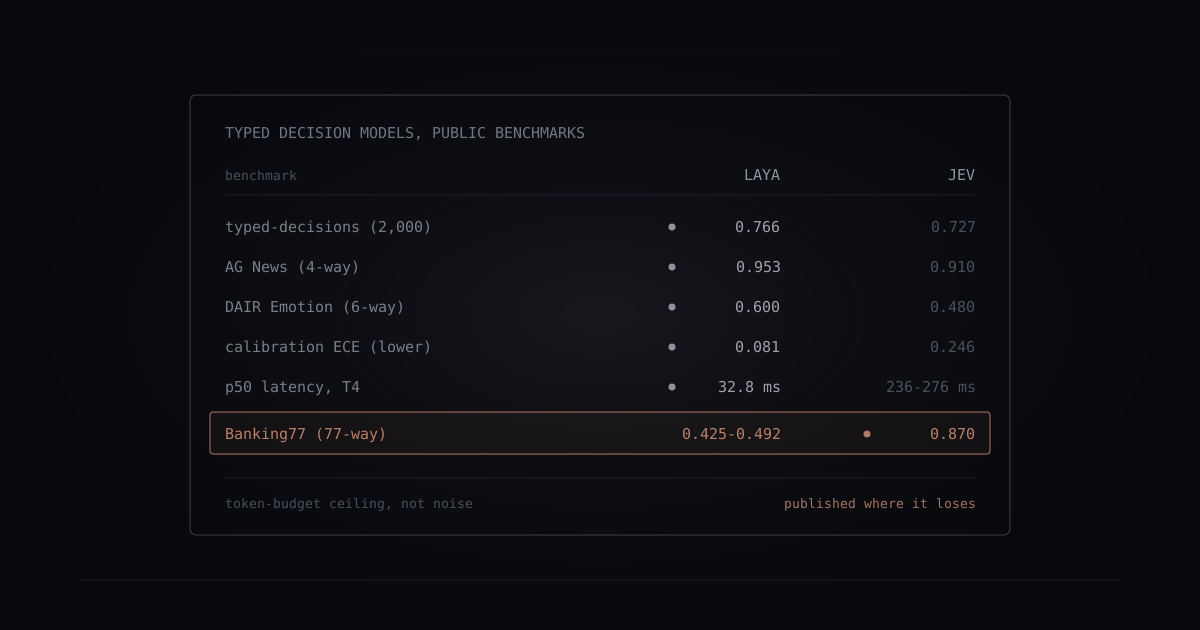
Laya vs Jev: an open-source benchmark of typed decision models
We benchmarked open-source Laya against TypeSafe's Jev on public datasets and internal scenarios: accuracy, latency, calibration, and where each wins.
LLM EvaluationAI EngineeringModel Selection
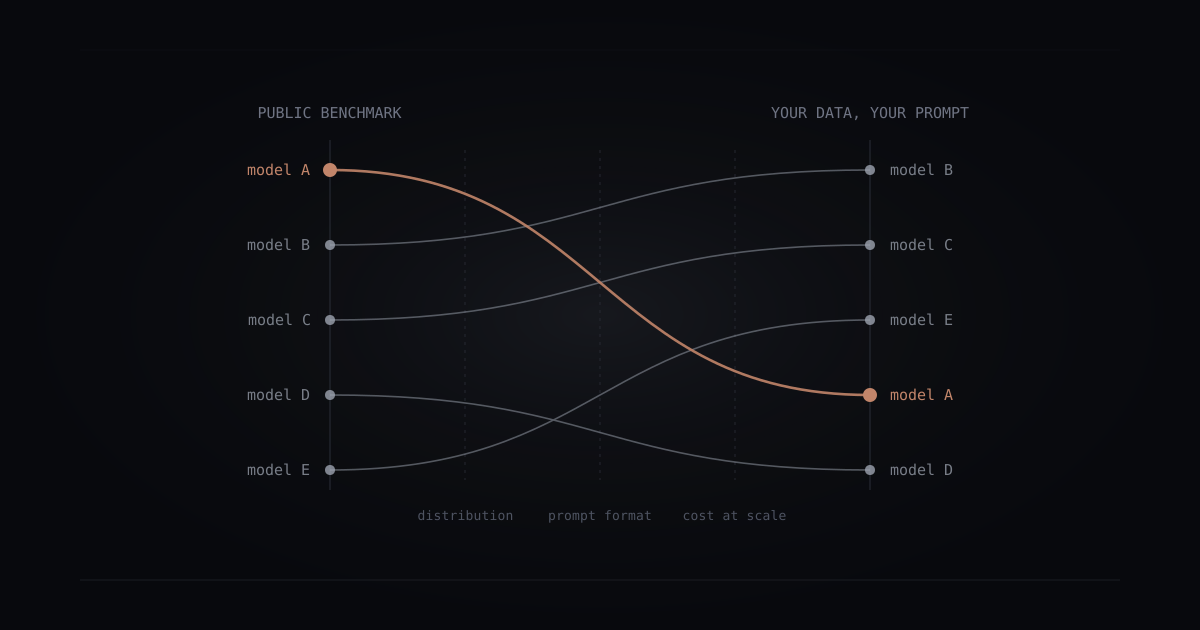
Evaluating LLMs for production: what benchmarks don't tell you
Public benchmarks measure models under controlled conditions. How to build an evaluation on your data and quality criteria that predicts production outcomes.
LLM EvaluationAI EngineeringProduction AIAI ArchitectureModel Selection